John Howard | CEO
Sensus AI
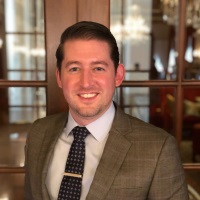
Dr. John Howard is a computer scientist specializing in the testing and evaluation of artificial intelligence and biometric systems, with a focus on bias, operational performance, and the interaction between automated systems and human decision-making. He has served as principal investigator on numerous research and development efforts across industry and government, holds multiple patents in biometric and AI enabled technologies, and has authored more than 30 scientific publications.
Dr. Howard is the Founder and CEO of Sensus AI, an independent AI testing and evaluation firm that helps organizations measure performance, bias, reliability, and operational risk in high-stakes AI systems. He previously served as Chief Data Scientist at the U.S. Maryland Test Facility, a leading AI test and evaluation facility for the U.S. Department of Homeland Security. In that role, he designed and led large-scale biometric technology evaluations supporting DHS operational missions, including programs focused on multimodal biometric recognition, identity card validation, presentation attack detection, and operational system performance.
He currently serves as editor of ISO/IEC 19795-10 and ISO/IEC 19795-6, the international standards for testing bias in biometric systems and evaluating the performance of deployed biometric technologies. He has also served as an expert witness in legal matters involving data privacy regulations, patent disputes, and the forensic use of face recognition in the United States, and he holds an academic
appointment at Southern Methodist University’s AT&T Center.
Appearances:
Identity Week America - Day 1 @ 16:45
Beyond the benchmark: Five things AI testing needs for the modern era
AI testing has come a long way. We have moved from evaluating algorithms against static datasets and reporting a handful of accuracy metrics to increasingly sophisticated assessments of bias, robustness, security, and real-world performance. But the systems we are deploying, and the environments in which they operate, are evolving even faster.
This talk looks at how AI testing has evolved and proposes five things we need to do next to bring testing into the modern era. Drawing on lessons from biometric and operational AI evaluation, it will explore the need to move beyond benchmark accuracy, test systems rather than models, evaluate performance under realistic operating conditions, continuously probe for failures and emerging threats, and translate technical results into evidence that decision-makers can actually use.
GET INVOLVED AT IDENTITY WEEK AMERICA
Created by
Terrapinn is proud to be a member of isla.
Working together to build sustainable events