Loren Perelman | Vice President of Customer Experience
ZONTAL
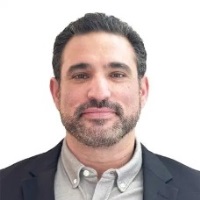
Dr. Loren Perelman is a technology and business executive specializing in scientific data, digital transformation, and customer experience for the life sciences industry. As Vice President of Customer Experience at ZONTAL, he leads global customer delivery, professional services, and customer success, helping some of the world's largest pharmaceutical and biotechnology organizations transform complex scientific data into strategic business assets. With more than two decades of experience spanning biotechnology, software, and enterprise transformation, Loren has built and led high-performing organizations responsible for large-scale implementations, scientific data integration, digital laboratory modernization, and operational excellence. His career uniquely combines deep scientific expertise—including a Ph.D., published research, and multiple patents—with executive leadership in enterprise software, enabling him to bridge the gap between science, technology, and business strategy.
Appearances:
BioTechX EU Day 1 @ 15:50
From Paperless Labs to Defensible Decisions: Evidence Infrastructure for Scientific AI
Pharmaceutical research and development (R&D) laboratories have made major progress toward paperless workflows. Electronic lab notebooks, laboratory information management systems (LIMS), and chromatography data systems capture measurements digitally. Yet when a model flags an atypical impurity trend or recommends a formulation change, scientists often cannot trace that recommendation through instrument calibration, method validation, sample history, and study context to the original measurements. The data is digital; the evidence chain remains fragmented.
This keynote introduces evidence infrastructure: governed, bidirectional provenance created as data flows from instruments to scientific decisions. Grounded in the ICAD Principles (Integrate → Contextualize → Analyze → Decide), each integration enriches a scientific context graph. Typed relationships link analytical results to methods, specifications, stability protocols, batch genealogy, instrument state, and regulatory submissions. As these connections accumulate, the context graph becomes an operational knowledge graph whose conclusions remain traceable to source evidence.
The talk shows why evidence chains should be created during ingestion rather than reconstructed for each AI deployment, and how this supports scientific review, human oversight, and evolving transparency expectations. Attendees will leave with practical architectural patterns for assessing whether their digital lab produces accessible data alone or defensible evidence for scientific AI.
Get involved at BioTechX Europe
Created by
Terrapinn is proud to be a member of isla.
Working together to build sustainable events